2025 · CONNECTORS
Greek Parliament Speeches Analysis (1989–2020)
A data analysis and information retrieval project analyzing over 1.2 million speeches from the Greek Parliament (1989–2020).
- Python
- Pandas
- NumPy
- NLTK
- scikit-learn
- Flask
- HTML
- CSS
- JavaScript
- Problem
- 1,280,918 Greek Parliament speeches from 5,355 sessions (1989–2020) sat in a single 2.30 GB CSV: too large to read, search or compare.
- What I built
- With my team, a search engine over the speeches plus keyword extraction with trends over time, similarity between MPs, LSI topic analysis and clustering, served through a Flask web app.
- Result
- Three decades of political speech became searchable by keyword, speaker or date, with the main topics and the most similar MPs visible at a glance.
This project was developed for the “Information Retrieval” course.
It focuses on analyzing all speeches from the Greek Parliament between 1989 and 2020.
Dataset
The dataset, sourced from the Hellenic Parliament’s website, contained 1,280,918 speeches by Greek MPs (2.30 GB total), extracted from 5,355 parliamentary sessions.
Each record included metadata such as the speaker’s name, political party, date, and session details.
The dataset was provided in a UTF-8 encoded CSV file and served as the foundation for multiple analytical tasks.
Implementation Highlights
- Web-Based Search Application:
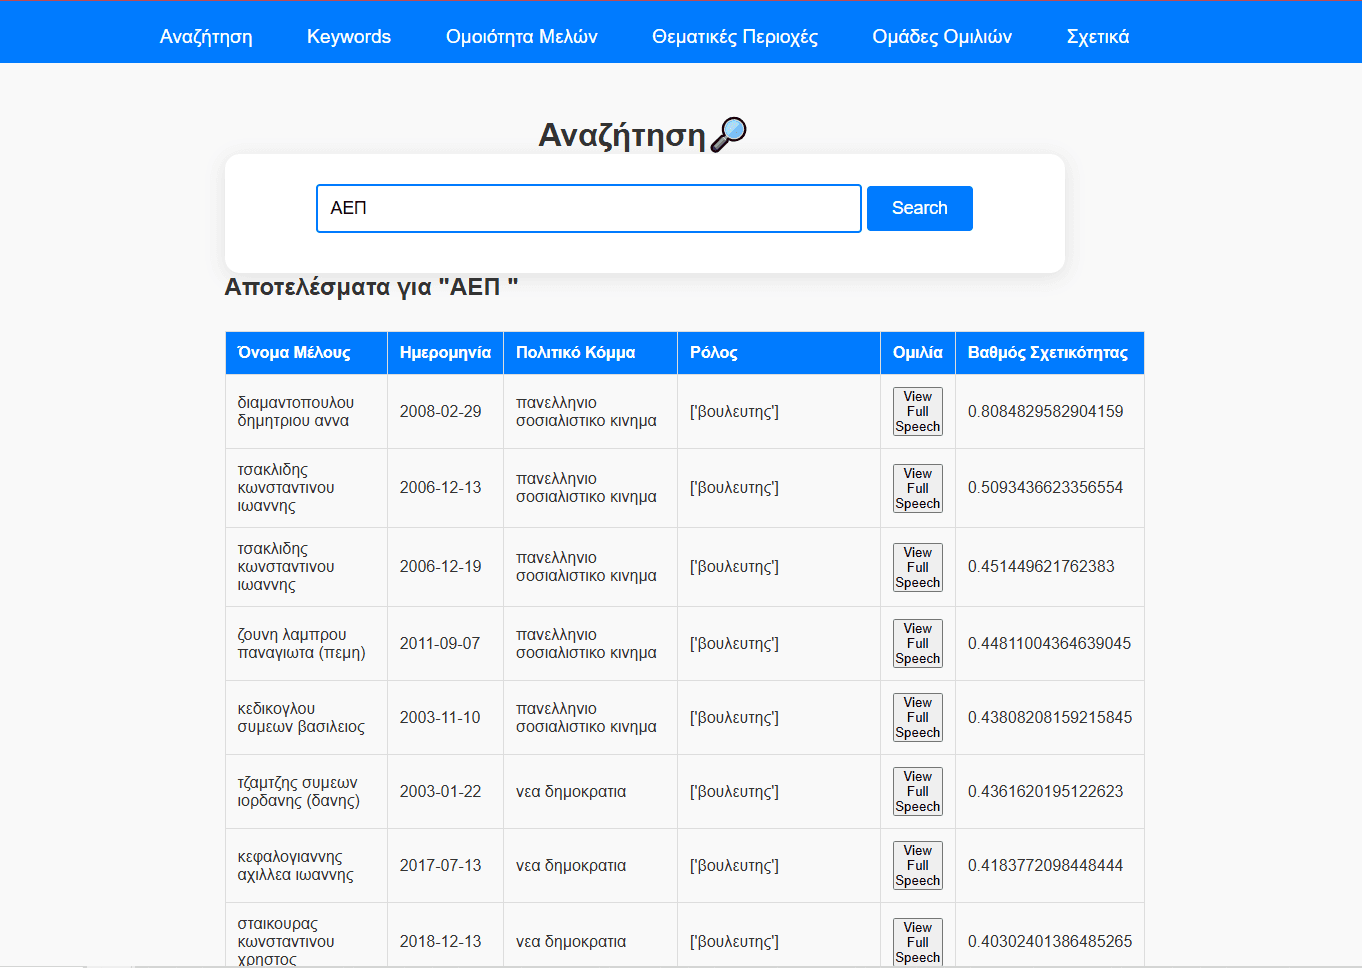
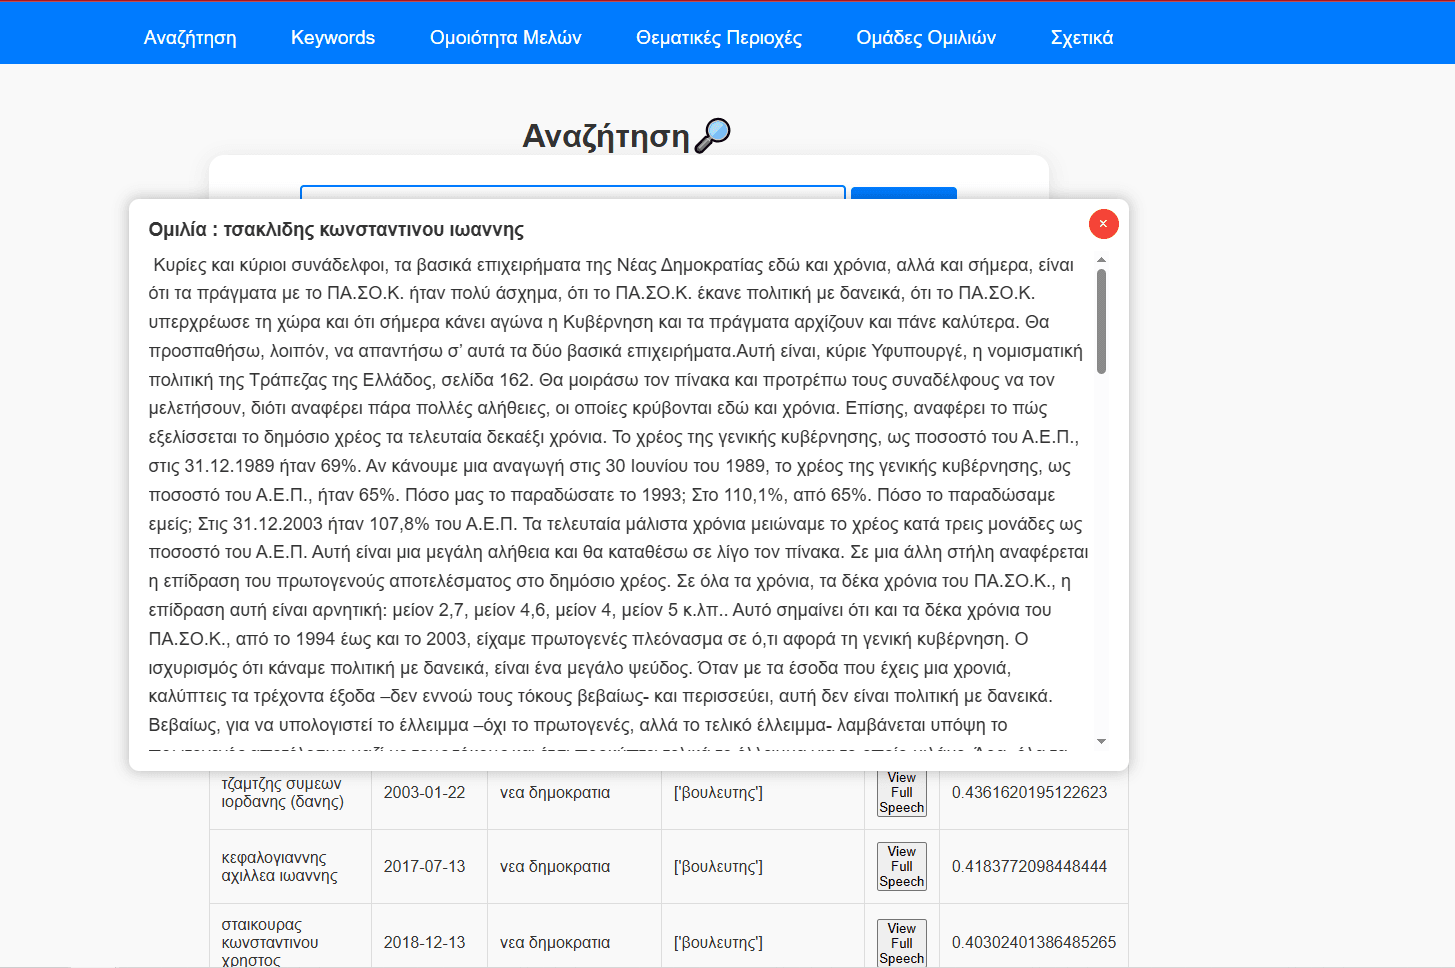
Developed a web interface functioning as a custom search engine for the dataset, allowing users to query and retrieve speeches by keywords, speaker, or date range.
- Keyword Extraction & Temporal Analysis:
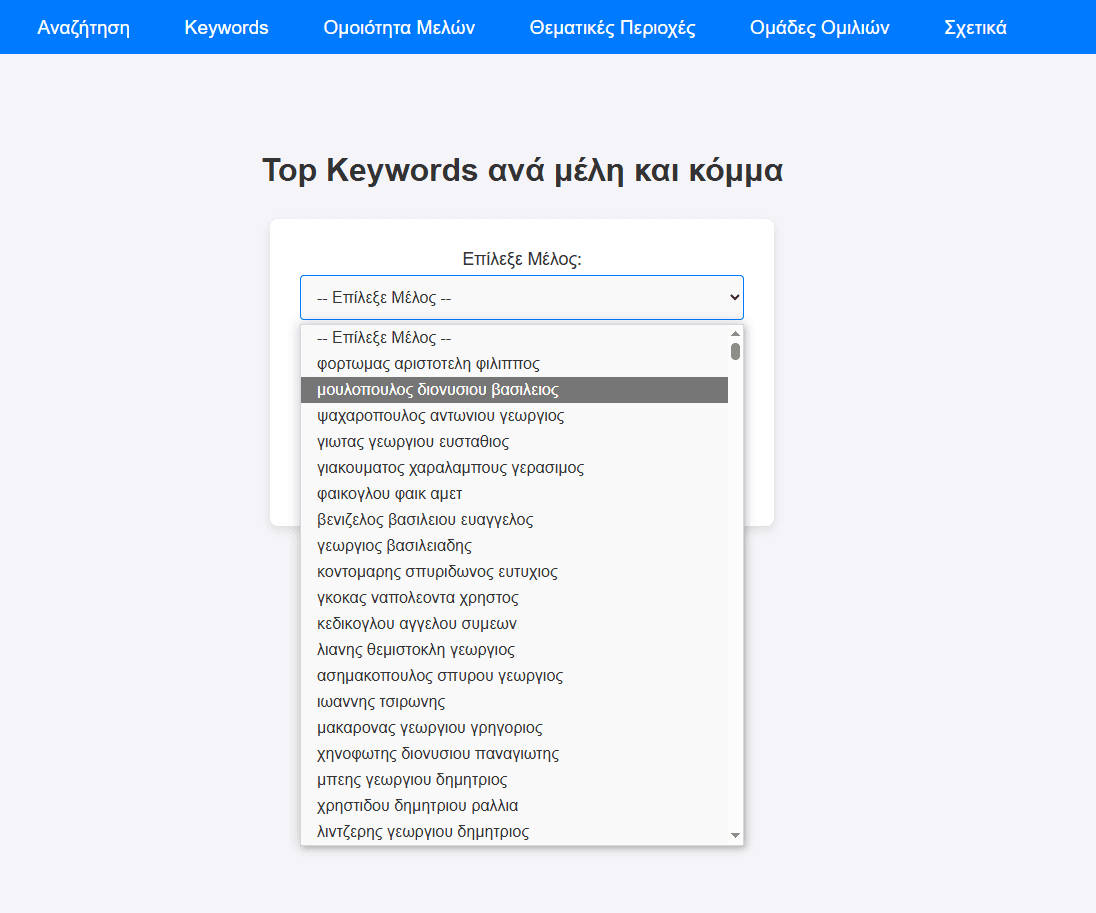
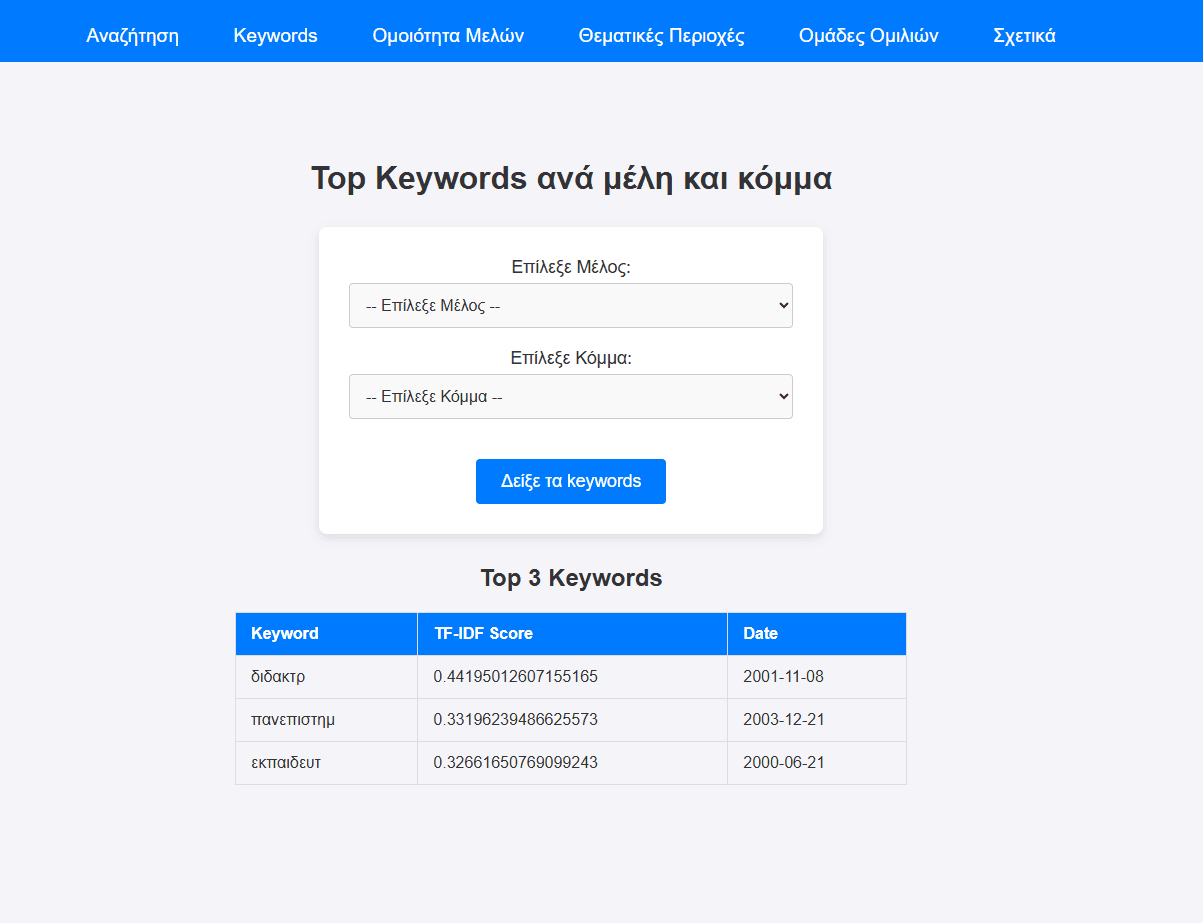
Implemented algorithms to extract the most significant keywords for each speech, MP, and party, followed by time-based trend analysis of these keywords to visualize their evolution.
- Similarity Detection Among MPs:
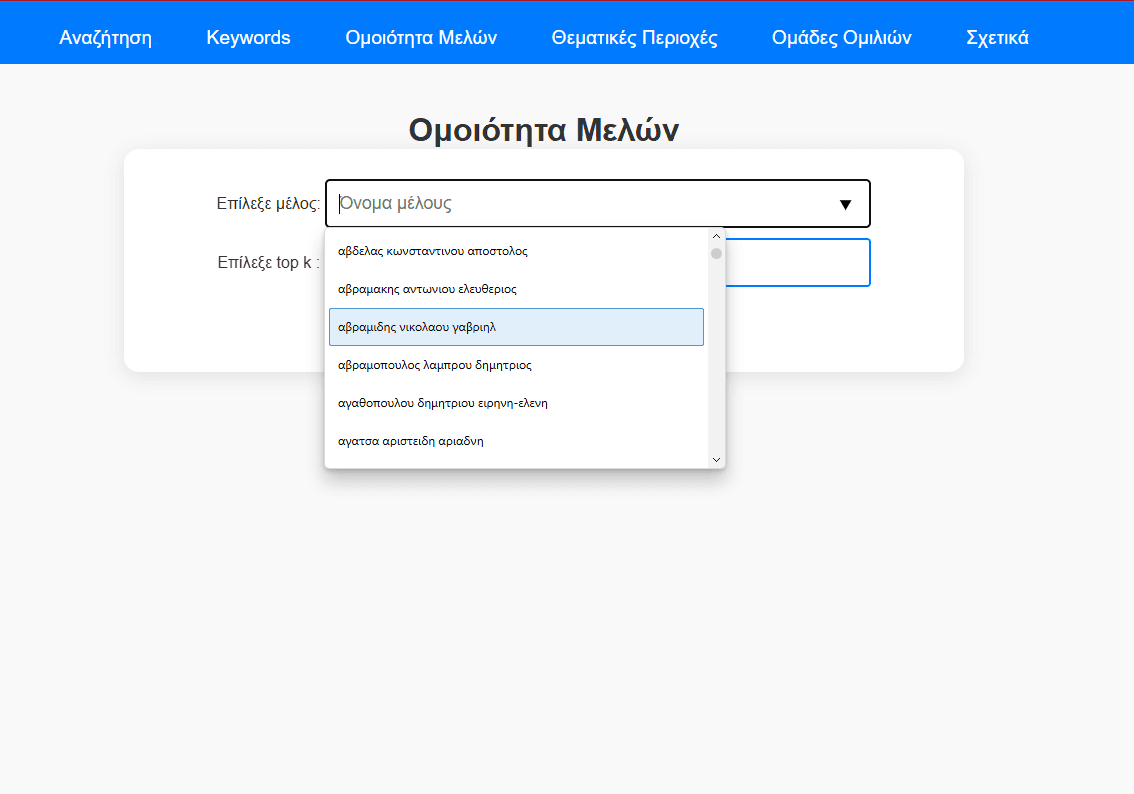
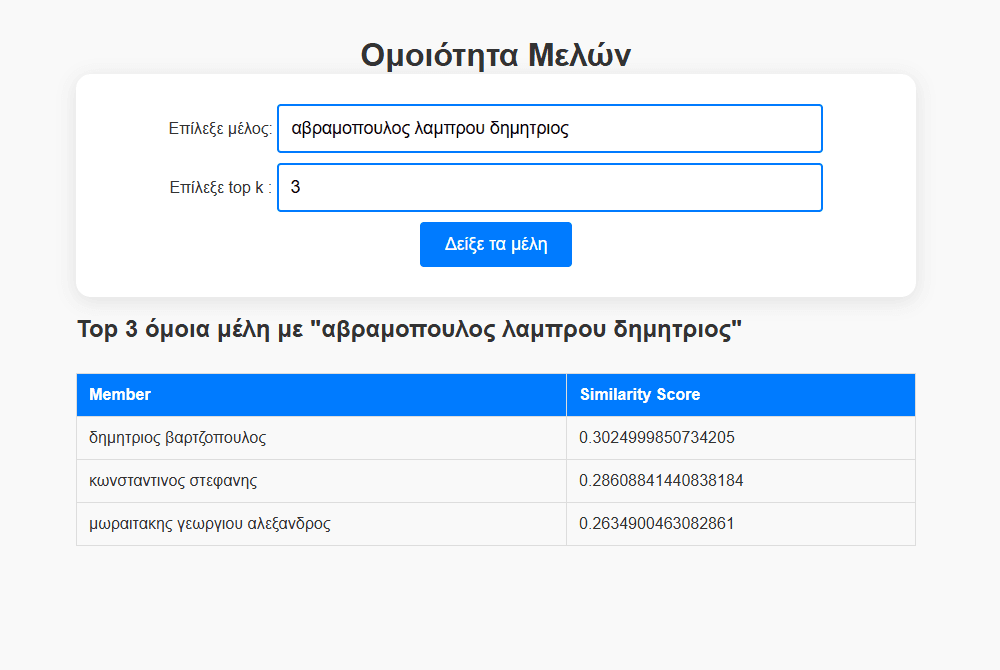
Represented each MP’s speeches as feature vectors and computed pairwise similarities, identifying the top-k most similar MPs based on their speech content.
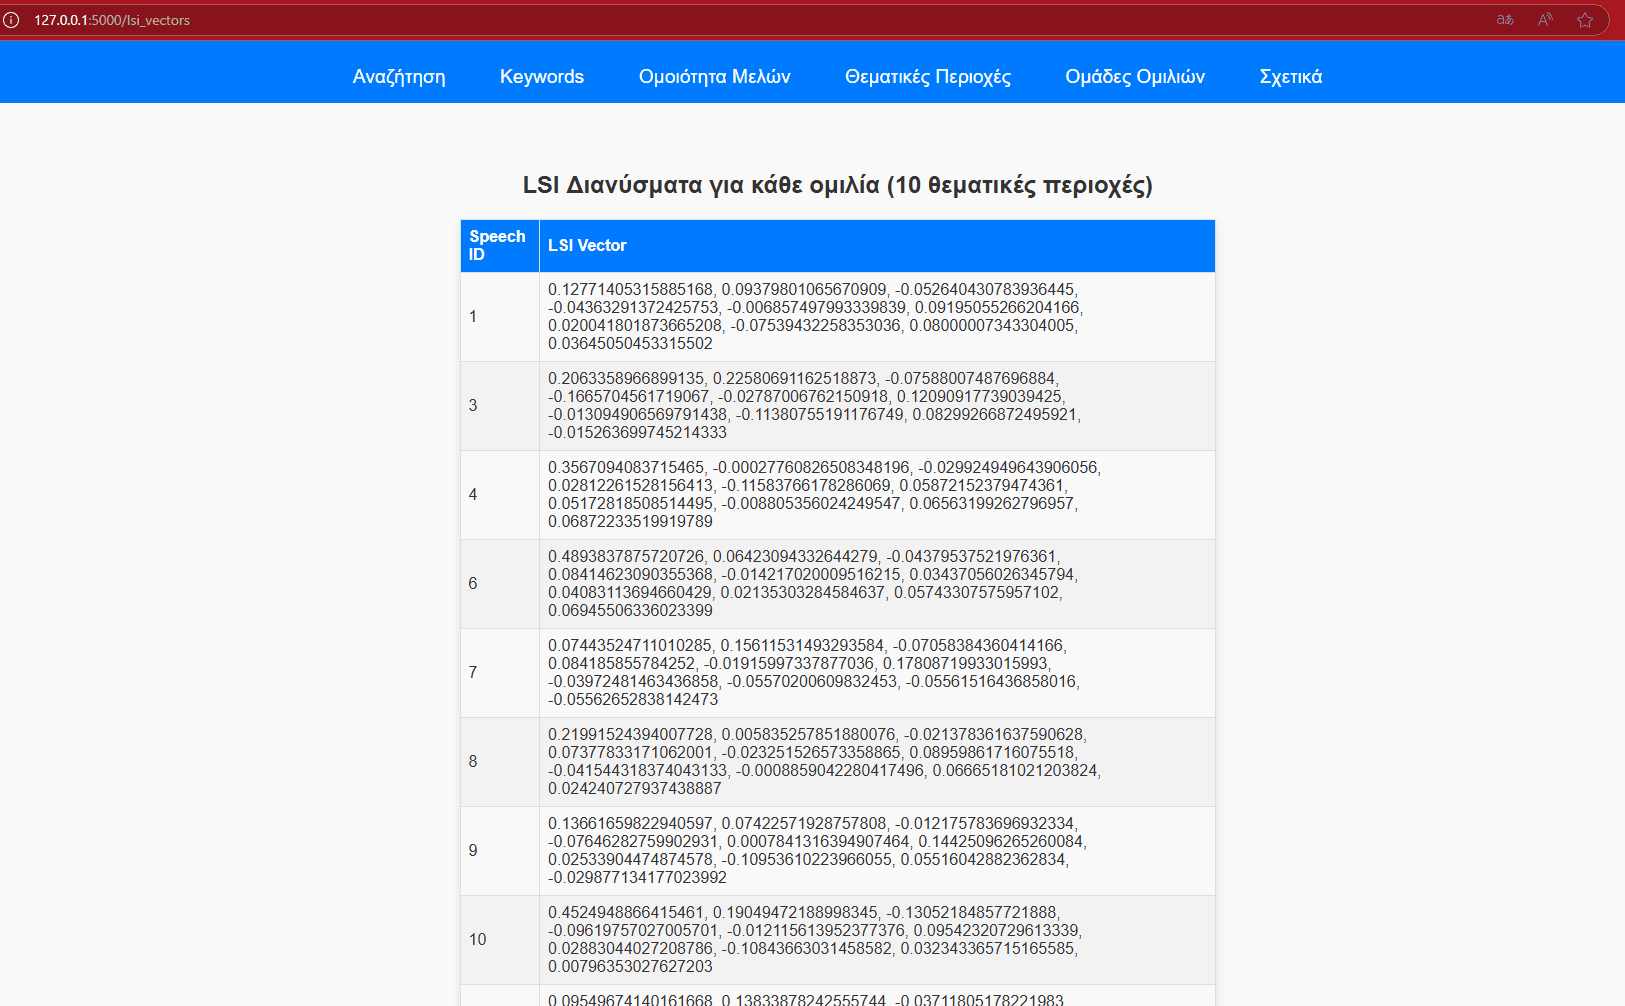
- Latent Semantic Indexing (LSI):
Applied LSI to uncover latent thematic structures across all speeches, enabling dimensionality reduction and clustering of semantic topics.
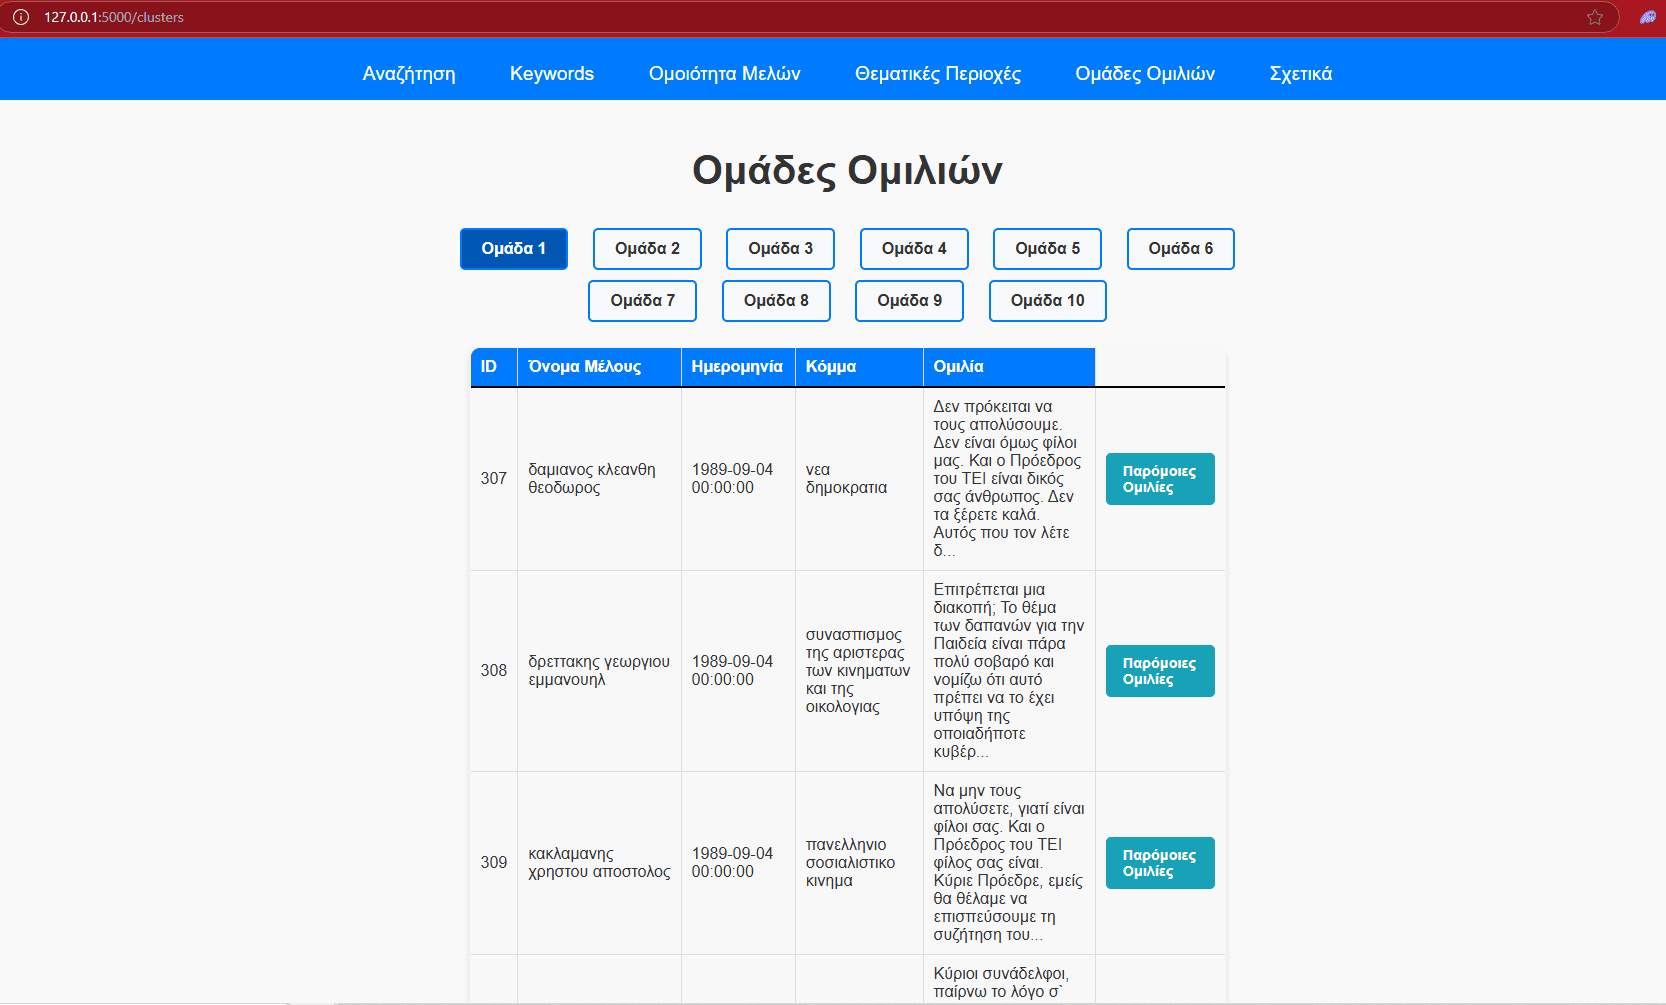
- Clustering of Speeches:
Grouped speeches into clusters with high internal similarity, revealing distinct political themes and discussion patterns.
- Custom Additional Task:
Designed and implemented an extra analysis proposed by our team, offering unique insights derived from the dataset and extending beyond the required coursework.
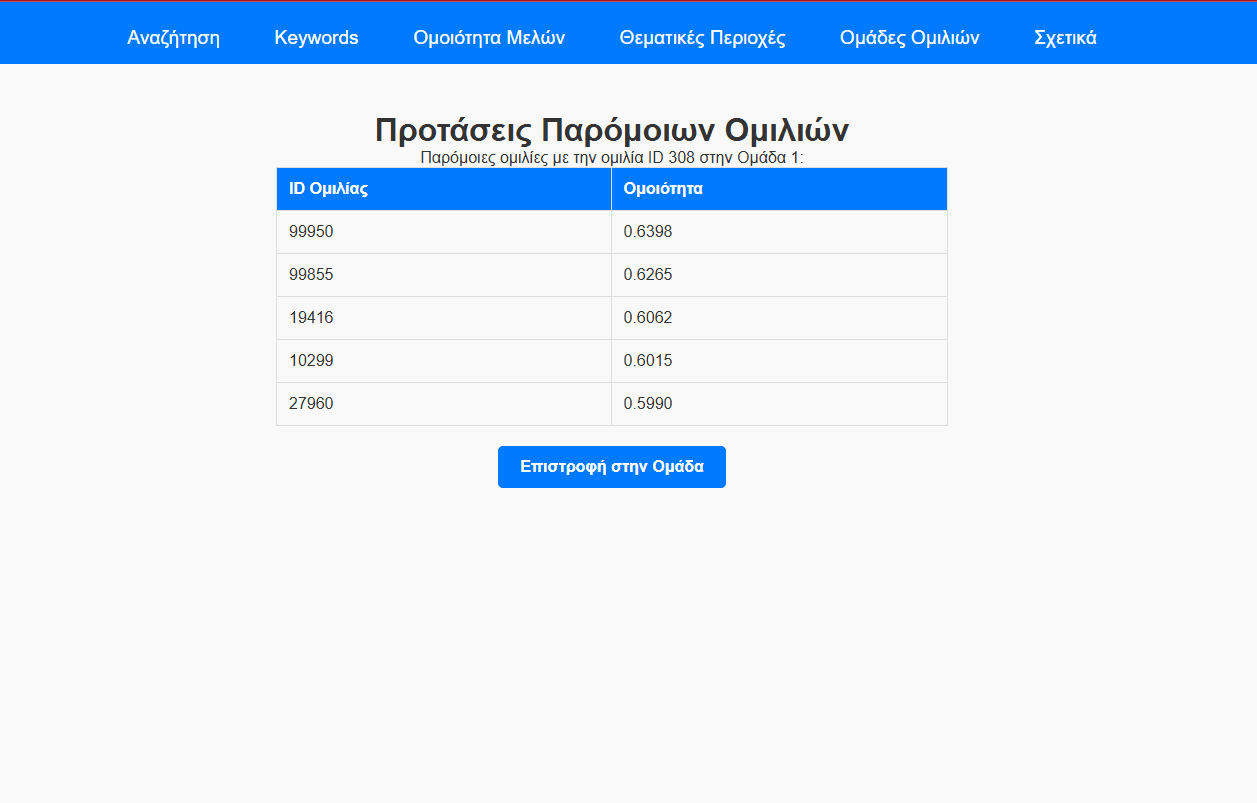
This project demonstrates advanced skills in data analysis, information retrieval, and natural language processing, combined with practical implementation through a web-based analytical platform.